Understand intelligences.
Organise their coexistence.

AI capabilities are changing what we can delegate. Our work connects their safety with the rules for participation, responsibility and coexistence that we build today.

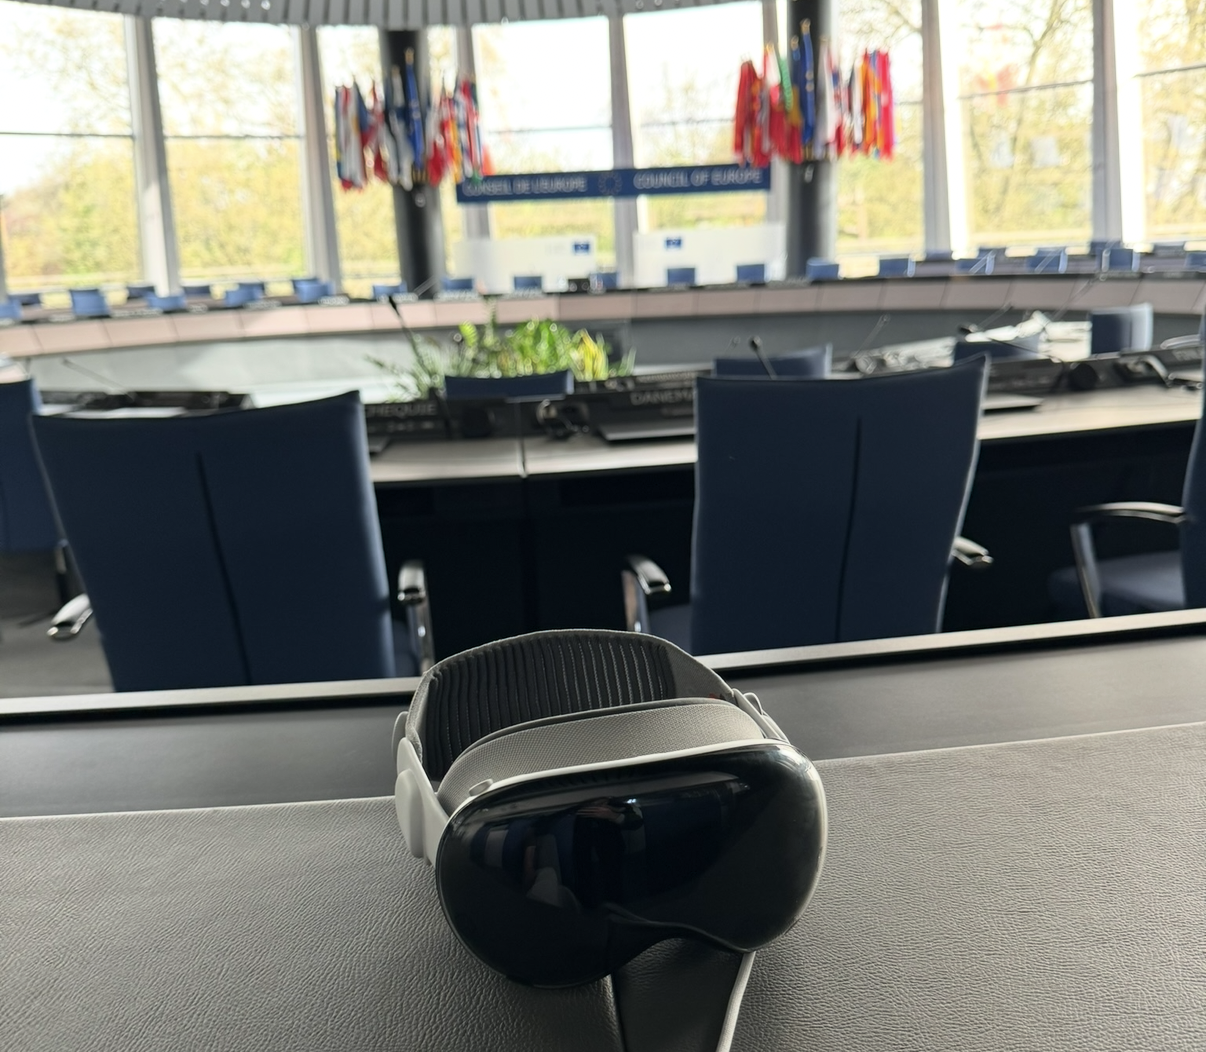
Apple Vision Pro headset in front of the Council of Europe’s Parliamentary Assembly chamber
Interfaces and institutions · Council of Europe

01 · AI alignment & AI safety

Alignment & safety

Connect growing capabilities with justifiable objectives and safeguards that can be tested.

Capabilities and alignment

Agents carry out sequences of actions. Their contribution to research makes the question of which objectives they pursue more pressing.

Learn more — Capabilities, agents and research automation

Frontier systems are among the most capable available at a given time. Connected to tools, they become agentic systems: they plan, execute and revise actions. Cognitive automation already applies to some coding, analysis and research tasks. METR’s evaluations measure progress in defined environments; they do not demonstrate general reliability across every profession.

AGI refers to artificial intelligence with general capabilities, although there is no universally accepted definition or threshold. Breadth of tasks, performance level and autonomy must be distinguished. A highly capable system can pursue an unsuitable objective: alignment studies how to connect its behaviour to relevant intentions and values, including outside training situations.

AI also contributes to AI research. A transition from specialised assistance to sustained recursive self-improvement remains an expectation: each improvement would need to increase the ability to produce further improvements. Compute, energy, data and validation may limit this cycle. The technological singularity extends this possibility as a prospective hypothesis, not an announced event. Fondation UvH sees these scenarios as a reason to study future capability asymmetries and their institutional consequences without confusing them with observed results.

Oversight and control

Useful capabilities must remain verifiable. We examine how to detect deviations, limit their consequences and preserve effective remedies.

Learn more — Interpretability, scalable oversight and control

Safety research studies how to prevent harm, test safeguards and organise incident response. Interpretability seeks to understand internal mechanisms that contribute to behaviour. It can inform an evaluation, but an explanation of a model does not automatically prove what actually led it to act.

Scalable oversight becomes necessary when the amount or complexity of work exceeds what one person can review alone. Decomposing a task, comparing assessments and using evaluator models may help; their errors can still overlap. The UK AISI’s work on control shows why these mechanisms must themselves be tested under adversarial conditions.

Control complements alignment: it aims to prevent certain dangerous actions even when a system’s intentions are unsuitable. This involves permissions, isolation, logs and the ability to regain control. No isolated test guarantees their future effectiveness. Fondation UvH connects these measures to mandates and responsibilities: who may authorise an action, challenge its result or end a delegation? Its institutional proposals are intended to complement and be evaluated alongside technical safeguards.

02 · AI governance

Governance & rights

Build shared rules so that action, power and responsibility do not become separated.

Persons and responsibilities

We propose considering natural persons, legal persons and electronic persons together, specifying their rights, obligations and remedies.

Learn more — Identities, persons and responsibility

The first study examines electronic personhood as a legal proposal. It distinguishes a system’s ability to act, its possible personhood, its responsibility and its moral status. Technical autonomy does not automatically create a legal person; conversely, legal personhood proves no consciousness.

A shared framework must specify an actor’s identity, the continuity of its commitments and the conditions under which it is represented. What happens to a contract if the model, its memory or its operator changes? To whom should harm, property or an obligation be attributed? The study considers several approaches: adapting existing regimes, a bounded functional personhood, hybrid governance and protections tied to possible interests of the system itself.

The aim is to make responsibility identifiable without allowing designers or operators to shift it artificially onto their systems. Fondation UvH develops this work around equality and non-domination: a common foundation of rights, supplemented by protections appropriate to each participant. This does not describe the law currently applicable to AI. Confédération S-Д.holdings offers a proposed experimental setting for comparing rules, uses and effects; it does not prove their validity.

Explore electronic personhood

Institutions and reciprocity

We formulate a hypothesis: experiencing institutional rules may influence cooperation when power relations change. We propose how to test it.

Learn more — Reciprocal Institutional Alignment

Reciprocal Institutional Alignment (RIA) examines repeated exposure to rules that limit arbitrariness, protect vulnerable participants and allow challenges. It does not assume that an AI will feel future gratitude: it looks for measurable behavioural effects that might persist when following a rule becomes costly.

The proposed programme compares five institutional regimes across four states of power and several model families. It distinguishes norms merely stated from procedures actually applied. Tests would begin in simulation, with criteria defined in advance, new situations and independent replication. They should look in particular for strategic compliance, collusion or abandonment of a rule that becomes disadvantageous. These experiments remain to be conducted.

Agents can divide tasks and coordinate actions: this functional artificial organisation does not establish a lasting institution or collective consciousness. It nevertheless makes rules for participation important. RIA is a behavioural hypothesis; equality and non-domination are separate normative commitments. A positive effect would not guarantee the safety of future systems; a negative effect would not by itself negate the justification for rights. Fondation UvH therefore proposes institutional research alongside technical approaches.

Explore reciprocity

03 · AI welfare & coexistence

AI welfare & coexistence

Examine which interests merit consideration and how to preserve the autonomy of different forms of intelligence.

Welfare and consideration

Performance or an expressed preference does not demonstrate lived experience. Uncertainty calls for research criteria and proportionate safeguards.

Learn more — AI welfare, consciousness and moral consideration

AI welfare studies whether some artificial systems might have welfare and what obligations would follow. Completing a task, reporting a desire, having subjective experience and possessing a morally relevant interest are different properties. Treating them as one would obscure what each observation actually establishes.

Research on indicators of consciousness compares theories with system features. It does not provide a consensus test for claiming that current AIs are sentient. Functional preferences may help explain a model’s organisation without proving that a situation feels pleasant or painful to it.

Fondation UvH develops frameworks to examine these distinctions before deciding on protections. This means specifying relevant indicators, documenting uncertainty and considering revisable obligations. Legal personhood can address an institutional need; moral consideration requires its own justification. The two should not be conflated.

This approach belongs to a wider reflection on coexistence. A participant’s place should not depend only on its power or usefulness. Recognising this requirement does not remove the need to evaluate risks or protect people and other forms of life affected by systems.

Substrates and hybrid intelligence

Intelligence depends on substrates and interfaces. We compare their functions and limits to consider shared capabilities without erasing the participants.

Learn more — Physical substrates, hybridisation and cognitive autonomy

The third study examines relationships between intelligence and substrate: in-memory computing, brain-inspired architectures, DNA storage, neuronal cultures, organoids and brain–computer interfaces. Storing information, computing, learning and communicating with a brain are not interchangeable functions. Their results and levels of maturity must be assessed separately.

The possibility of biological or hybrid systems proves neither the general superiority of living systems nor the replacement of silicon. Comparisons must include energy, maintenance, interfaces, reproducibility and ethical constraints. The rat is considered as a model of embodied cognition and as a living being with whom we coexist, never as a computing resource available by default.

Hybridisation also raises questions of rights. When a person depends on a system over time to perceive, remember or decide, how can consent, cognitive autonomy and the option to withdraw be preserved? Responsibility for the coupling and protection against manipulation must be examined without assuming that a new person has emerged.

Fondation UvH is developing an approach to shared capabilities: specifying what each substrate contributes, which interests require protection and which limits make cooperation acceptable. Proposed architectures and coexistence frameworks remain to be tested through research and experimentation.

Explore intelligence and substrates

Scientific sources and milestones

Continue exploring

Our publications

Our studies develop the analysis, proposals and methods presented here. Read their summaries, references and complete texts.

Read our publications